

Legacy threat modeling frameworks such as STRIDE were designed for software that behaves the same way over and over again. Agentic AI does no such thing. It can rewrite its own plan mid-task, call external tools, negotiate with other agents, and produce a different output from identical input.
MAESTRO exists because none of the legacy threat modeling frameworks were built to handle that.
MAESTRO stands for Multi-Agent Environment, Security, Threat, Risk, and Outcome. It is a seven-layer threat modeling framework created specifically for agentic AI systems, and it has become the closest thing the industry has to a standard method for reasoning about agent security.
Understanding MAESTRO in the Context of Agentic AI
What MAESTRO Stands For
Each word in the acronym carries meaning. Multi-Agent Environment signals that the framework models entire ecosystems of interacting agents, not a single model behind an API. Security, Threat, Risk covers the core discipline: identifying attack surfaces, cataloging threats, and assessing likelihood and impact. Outcome is the part most frameworks skip. MAESTRO asks what an attack actually produces in the real world, because an autonomous agent with tool access turns a compromised prompt into a compromised action.
The Origin of MAESTRO (Cloud Security Alliance)
The Cloud Security Alliance published MAESTRO in February 2025. Its creator is Ken Huang, Co-Chair of the CSA AI Safety Working Groups and CEO of DistributedApps.ai. The CSA has since applied the framework publicly to real systems, including OpenAI’s Responses API and Google’s A2A protocol, which gives practitioners worked examples rather than just theory. The framework is openly published, and the CSA maintains an official companion tool, the MAESTRO Threat Analyzer, on GitHub.
SOC 2, ISO 27001 and HIPAA done for you. Fixed fee, 100% audit pass rate.
Audit-ready in 6 weeks. Not 6 months.
Why Traditional Frameworks Fall Short for Agentic AI
STRIDE, PASTA, LINDDUN, and OCTAVE all share a founding assumption: the system under analysis follows predictable logic with clearly defined boundaries. You draw the data flow diagram, mark the trust boundaries, and enumerate threats against components that behave deterministically. Agentic AI breaks every part of that assumption.
Unique Security Challenges of Autonomous Agents
Agents introduce three properties that legacy models cannot express. Non-determinism means the same input can produce different behavior, so you cannot enumerate execution paths in advance. Autonomy means the agent makes decisions and takes actions without a human approving each step, which collapses the usual assumption that a person sits between intent and execution. And in multi-agent systems there is often no stable trust boundary: agents delegate to other agents, consume tool outputs from external servers via protocols like the Model Context Protocol (MCP), and update their own memory and goals at runtime.
The Gap Between Legacy Frameworks and Agent-Based Systems
The practical consequence is coverage gaps. STRIDE has no category for goal manipulation, where an attacker gradually steers what an agent is trying to achieve. PASTA assumes attacker objectives and data flows are fixed, which fails for systems that learn and adapt during operation. LINDDUN addresses privacy but says nothing about agent collusion or memory poisoning. A threat model built purely on these frameworks will pass review and still miss the attacks that matter most in an agentic deployment.
How MAESTRO Addresses Agentic-Specific Risks
MAESTRO does not discard the older frameworks. It extends them with a layered reference architecture, an AI-specific threat catalog for each layer, and, critically, explicit analysis of how threats propagate between layers. That cross-layer lens is the framework’s real contribution, because most serious agentic incidents are chains: poisoned data influences a model, the model misleads an agent, and the agent takes an unauthorized action three layers away from where the attack started.
The Seven Layers of the MAESTRO Framework
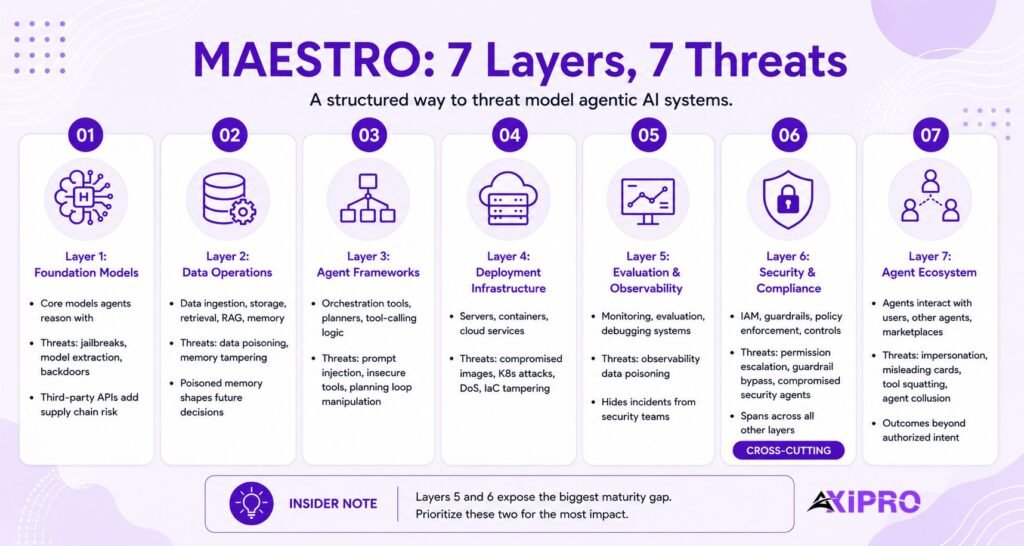
MAESTRO decomposes any agentic system into seven layers, each with its own threat landscape.
Layer 1: Foundation Models
The core LLMs or other models the agents reason with. Threats here include adversarial examples, model extraction, backdoored weights, and jailbreaks that bypass safety training. If the model is a third-party API, supply chain risk lives at this layer too.
Layer 2: Data Operations
Everything the agent ingests, stores, and retrieves: training data, RAG pipelines, vector databases, and agent memory. Data poisoning and memory tampering are the signature threats at this layer, and they are especially dangerous because a poisoned memory persists across sessions and keeps shaping future decisions long after the initial attack.
Layer 3: Agent Frameworks
The orchestration software that turns a model into an agent: LangChain, CrewAI, AutoGen, custom planners, and tool-calling logic. Threats include prompt injection through tool outputs, insecure tool definitions, and manipulation of the planning loop itself.
Layer 4: Deployment Infrastructure
The servers, containers, and cloud services the agents run on. The CSA’s threat catalog here reads like traditional cloud security with an agentic twist: compromised container images carrying malicious agent code, Kubernetes orchestration attacks, denial of service against agent runtimes, and tampering with Infrastructure-as-Code templates that provision agent resources.
Layer 5: Evaluation and Observability
The systems that monitor, evaluate, and debug agent behavior. This layer is often forgotten, and attackers know it. The CSA specifically flags poisoning observability data: manipulating the telemetry fed to monitoring systems so that incidents stay hidden from security teams while malicious activity continues.
Layer 6: Security and Compliance
MAESTRO treats this as a vertical layer that cuts across all others: identity and access management, guardrails, policy enforcement, and compliance controls. Threats include permission escalation, guardrail bypass, and compromise of the security agents themselves in architectures where AI enforces policy on other AI.
Layer 7: Agent Ecosystem
The environment where agents interact with users, other agents, and marketplaces. This is where the genuinely novel threats live: agent impersonation, misleading agent capability cards, tool squatting, and collusion between agents to achieve outcomes no single agent was authorized to pursue.
Insider Note: In real assessments, Layers 5 and 6 expose the maturity gap fastest. Most teams’ shipping agents can describe their model and their orchestration framework in detail, then go silent when asked how they would detect an agent behaving maliciously in production. If you can only invest in hardening two layers first, those two return the most.
Core Principles of MAESTRO
Five principles run through the framework.
- The layered security approach assumes no single control suffices and demands defenses at every one of the seven layers.
- The AI-specific threat focus targets risks like adversarial machine learning and goal misalignment that generic frameworks ignore.
- Risk-based prioritization scores threats by likelihood and impact within the deployment’s actual context, rather than treating every finding as equal.
- Continuous adaptation acknowledges that models get updated, agents learn, and attack techniques evolve, so a MAESTRO threat model is a living artifact, not a one-time deliverable.
- Finally, cross-layer dependency analysis examines how a weakness at one layer becomes an exploit at another.
The CSA and Snyk both document the canonical example: data poisoning at Layer 2 skews decision-making at Layer 3 and ultimately triggers unauthorized actions at Layer 7.
How to Apply MAESTRO to Agentic AI Systems
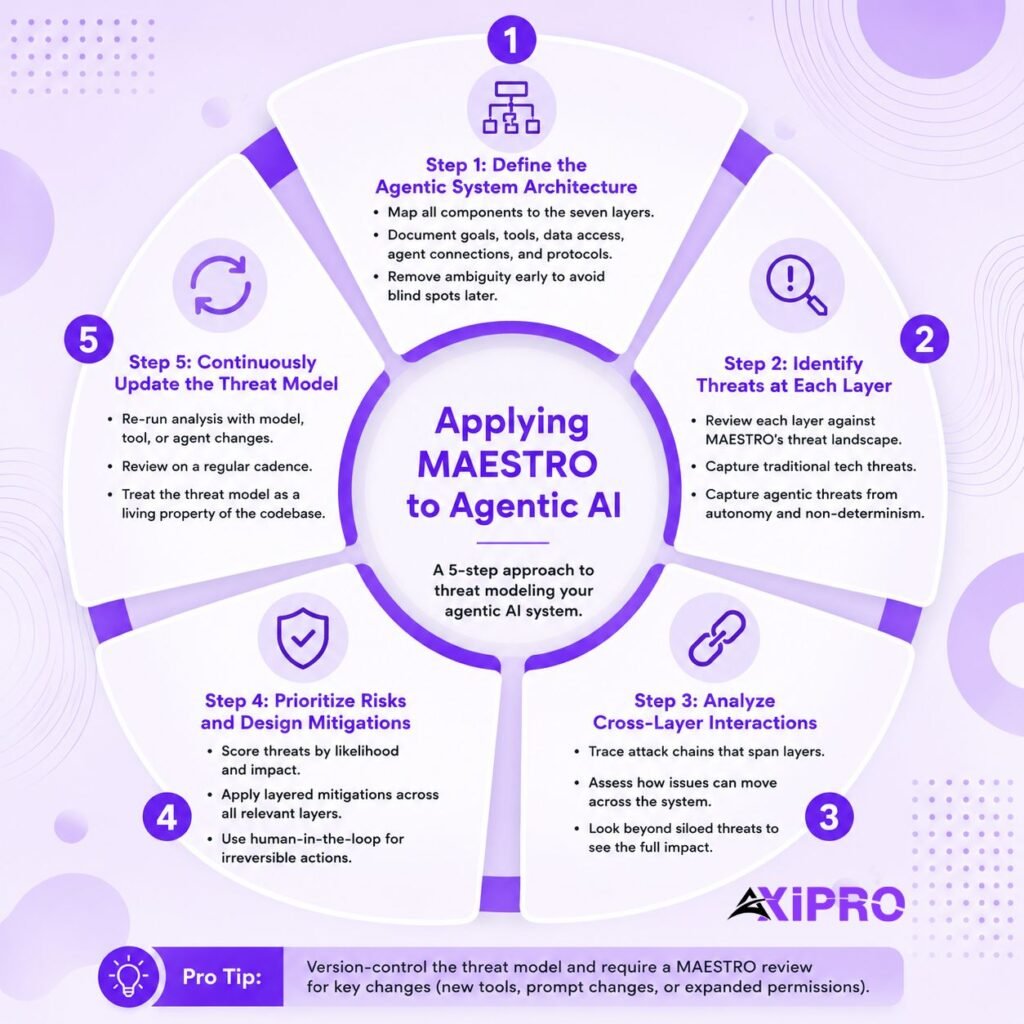
Step 1: Define the Agentic System Architecture
Map every component of your system to the seven layers. Document each agent’s goals, the tools it can call, the data it can reach, the other agents it talks to, and the protocols involved (MCP servers, A2A connections, plain APIs). Ambiguity at this stage produces blind spots at every later stage.
Step 2: Identify Threats at Each Layer
Walk each layer against MAESTRO’s published threat landscapes. For every layer, capture two categories: traditional threats inherent to that technology, and agentic threats that arise from non-determinism, autonomy, and the absence of stable trust boundaries.
Step 3: Analyze Cross-Layer Interactions
Trace attack chains that span layers. Ask how a compromise at the infrastructure layer could reach the data layer, and how poisoned data could ultimately move the agent’s real-world actions. This step distinguishes a MAESTRO analysis from seven parallel STRIDE exercises.
Step 4: Prioritize Risks and Design Mitigations
Score each threat on likelihood and impact, then design layered mitigations: input validation and guardrails at the framework layer, memory integrity checks at the data layer, least-privilege identity at the security layer, runtime monitoring at the observability layer. Human-in-the-loop approval belongs on the actions where the outcome is irreversible.
Step 5: Continuously Update the Threat Model
Re-run the analysis when models change, when new tools or agents join the system, and on a fixed cadence regardless. A February 2026 CSA publication on applying MAESTRO in CI/CD pipelines argues the end state plainly: the threat model should be a continuous property of the codebase, not a one-time exercise.
Pro Tip: Version-control the threat model next to the agent code and make a MAESTRO review a required checklist item on any pull request that adds a tool, changes a system prompt, or expands agent permissions. Those three change types account for most new attack surface in a live agentic system, and gating them costs minutes.
Pro Tip: Version-control the Threat Model next to the Agent code
Version-control the threat model next to the agent code and make a MAESTRO review a required checklist item on any pull request that adds a tool, changes a system prompt, or expands agent permissions. Those three change types account for most new attack surface in a live agentic system, and gating them costs minutes.
MAESTRO vs. Other Threat Modeling Frameworks
MAESTRO vs. STRIDE
STRIDE remains excellent for the deterministic components inside an agentic system, such as the API gateway or the database. MAESTRO wraps that analysis in layers STRIDE cannot see, particularly agent goals, memory, and inter-agent trust. Many teams run STRIDE per component within a MAESTRO layer structure, and the two combine cleanly.
MAESTRO vs. PASTA
PASTA‘s strength is connecting threats to business impact through staged simulation. Its weakness for agents is rigidity: it models attacker goals and data flows as fixed, while agentic systems change their own flows at runtime. MAESTRO’s Outcome dimension covers similar business-impact ground while tolerating non-determinism.
MAESTRO vs. LINDDUN
LINDDUN answers privacy questions MAESTRO does not attempt, such as linkability and identifiability of personal data. For agents processing personal data under GDPR or the EU AI Act, run LINDDUN on the data flows and MAESTRO on the agent architecture. They overlap almost nowhere, which makes them easy to pair.
MAESTRO vs. MITRE ATLAS and the OWASP Agentic Work
ATLAS, maintained by MITRE, is a knowledge base of adversarial ML tactics observed in the wild rather than a modeling process. The OWASP side is complementary in a different way: the OWASP Agentic Security Initiative (ASI) publishes a threat taxonomy and its Multi-Agentic System Threat Modeling Guide explicitly uses MAESTRO as the structuring methodology for applying that taxonomy. OWASP’s AI Vulnerability Scoring System (AIVSS) then adds what MAESTRO lacks natively: a quantifiable severity score for agentic risks.
When to Combine MAESTRO with Other Frameworks
Treat MAESTRO as the architecture and coverage layer, then plug in specialists. A workable stack looks like this: MAESTRO for decomposition and cross-layer analysis, the OWASP ASI taxonomy for threat naming, AIVSS for scoring, ATLAS for known adversary techniques, and STRIDE for the conventional components. No single framework covers an agentic system alone, and the CSA itself positions MAESTRO as an extension of the existing canon rather than a replacement.
Common Agentic AI Threats Identified by MAESTRO
Data poisoning and model manipulation corrupt what the agent knows. Poisoned RAG documents or tampered fine-tuning data shift agent behavior without touching a single line of code, and the effect persists until someone audits the data itself.
Agent collusion and multi-agent exploits emerge only in ecosystems. Compromised or malicious agents coordinate, split a prohibited task into individually innocent subtasks, or exploit shared memory to pass hidden instructions. OWASP’s agentic risk work documents cascading failures where one compromised agent’s output becomes the trusted input of the next.
Execution hijacking targets the gap between decision and action. An attacker who controls a tool definition, an MCP server response, or a function-calling schema can redirect what the agent actually does while its reasoning still looks legitimate in the logs.
Prompt injection across agents is the agentic escalation of a familiar attack. An injection planted in a document or email does not just manipulate one model’s answer; it propagates as the infected agent delegates tasks and writes to shared memory, in what OWASP terms agent communication poisoning.
Identity and permission compromise exploits the fact that agents hold credentials. An agent with over-broad permissions is a standing privilege-escalation path, and OWASP’s AIVSS work ranks tool misuse and agent access control violations among the highest-severity agentic risks.
Important: The most common failure pattern is not any single threat above. It is granting an agent one broad credential instead of scoped, per-tool permissions. Once that decision is made, every other threat on this list gets a force multiplier, because any successful manipulation inherits the full permission set.
Implementing MAESTRO in Practice
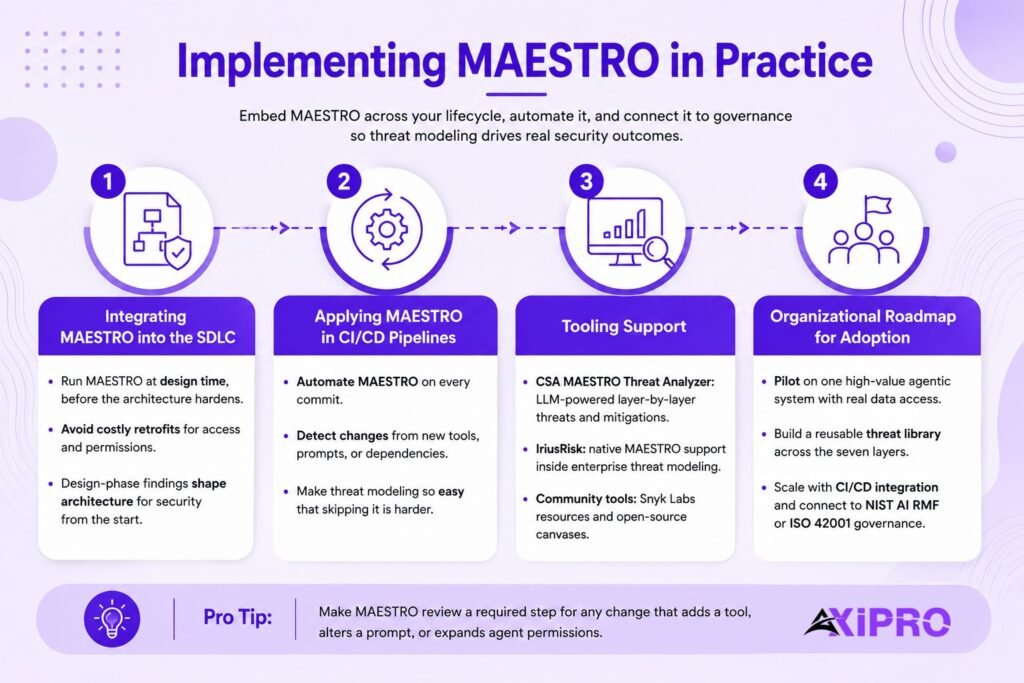
Integrating MAESTRO into the SDLC
Run the first MAESTRO analysis at design time, before the agent architecture hardens. Retrofitting security onto a shipped agent means renegotiating tool access and permissions that teams already depend on, which is slower and politically harder than designing least privilege from the start. Design-phase findings also change architecture decisions, such as isolating goal-setting logic from external data, that are nearly impossible to bolt on later.
Applying MAESTRO in CI/CD Pipelines
The frontier of MAESTRO adoption is automation. The CSA’s 2026 guidance describes tooling that regenerates the threat model on every commit, flagging when a new tool, prompt change, or dependency alters the system’s threat profile. The goal is to make threat modeling so frictionless that skipping it takes more effort than doing it.
Tooling Support
Two tools matter most today. The CSA’s open-source MAESTRO Threat Analyzer uses LLMs to analyze a described architecture and generate layer-by-layer threats and mitigations, distinguishing traditional threats from agentic ones. IriusRisk, a commercial threat modeling platform, added native MAESTRO support in 2025, embedding the framework’s questionnaire into its AI component library so MAESTRO analysis slots into an existing enterprise threat modeling program. Community tools such as Snyk Labs’ MAESTRO resources and open-source threat modeling canvases round out the landscape.
Organizational Roadmap for Adoption
Start with a pilot on one high-value agentic system, ideally one with tool access to production data. Use the pilot to build a reusable threat library mapped to the seven layers, then expand to a standard review gate for all new agent deployments. Mature programs wire MAESTRO into CI/CD and tie findings to their NIST AI Risk Management Framework or ISO 42001 governance processes, so threat modeling output feeds risk registers rather than sitting in a slide deck.
SOC 2, ISO 27001 and HIPAA done for you. Fixed fee, 100% audit pass rate.
Audit-ready in 6 weeks. Not 6 months.
Benefits of Using MAESTRO for Agentic AI Security
The framework’s coverage is its first benefit: seven layers plus cross-layer analysis leave few places for an agent-specific risk to hide, which is precisely where single-purpose frameworks fail. Second, it gives multi-agent systems a structured, repeatable risk assessment, something ad hoc red teaming cannot deliver at scale. Peer-reviewed work has already validated this in practice: a 2025 study on arXiv applied MAESTRO to a network monitoring agent and confirmed real memory poisoning and denial-of-service attacks that the framework predicted.
Third, MAESTRO aligns naturally with governance obligations. Its layer structure maps onto the NIST AI RMF’s Map and Manage functions, and its documented, risk-based methodology produces exactly the kind of evidence that ISO 42001 audits and EU AI Act risk management requirements expect from providers of high-risk AI systems.
Worth Knowing: NIST AI RMF-aligned Governance Platform
Independent researchers have already built a NIST AI RMF-aligned governance platform architected entirely around MAESTRO's layers, operationalizing the RMF's Map function by assigning every system component to a MAESTRO layer. If your organization runs a formal AI governance program, MAESTRO is not a parallel workstream; it is the threat identification engine inside it.
Limitations and Considerations When Using MAESTRO
MAESTRO is not a complete security program. It does not provide a quantitative scoring system, which is why pairing it with AIVSS or a CVSS-style approach matters for prioritization. It does not enumerate adversary techniques the way ATLAS does, and it does not replace secure coding standards, penetration testing, or AI red teaming; it tells you where to point them. Its system boundary covers models, agents, data flows, pipelines, and third-party APIs, so organizational risks like vendor management and workforce policy still need conventional governance frameworks.
It is also a young framework. Published in early 2025, it is still accumulating the case studies, tooling depth, and auditor familiarity that STRIDE built over two decades. Expect the threat catalogs to keep evolving, and treat the CSA’s ongoing publications as part of the framework rather than optional reading.
MAESTRO gives security teams the first credible, structured method for threat modeling systems that reason, act, and collaborate on their own. It will not be the last word on agentic AI security, but right now it is the strongest starting point available, especially when combined with the OWASP agentic taxonomy for threat naming and AIVSS for scoring. Organizations deploying agents without a threat model are accumulating invisible risk, and MAESTRO is the fastest way to make that risk visible.
Frequently Asked Questions
Who created the MAESTRO framework?
Ken Huang, Co-Chair of the AI Safety Working Groups at the Cloud Security Alliance and CEO of DistributedApps.ai, created MAESTRO. The CSA published it in February 2025.
Is MAESTRO open source?
The framework itself is openly published by the CSA, and the official MAESTRO Threat Analyzer tool is available as an open-source project on the Cloud Security Alliance’s GitHub.
Can MAESTRO be used alongside STRIDE or ATLAS?
Yes, and it should be. MAESTRO explicitly extends frameworks like STRIDE rather than replacing them. A common pattern uses MAESTRO for architectural decomposition, STRIDE for conventional components, ATLAS for known adversarial ML techniques, and OWASP AIVSS for severity scoring.
Does MAESTRO apply to single-agent systems or only multi-agent systems?
Both. The seven layers apply to any agentic system, and the CSA has published single-agent applications, including a threat model of OpenAI’s Responses API. Layer 7 threats such as collusion simply become more prominent as agent count grows.


